What OpenAI's Decisions API Does, and When Developers Might Use It
OpenAI's Decisions API returns typed probabilities, choices and scores for text and images. This explainer covers its public beta, the Responses API comparison, pricing, and the checks developers should run before relying on its outputs.
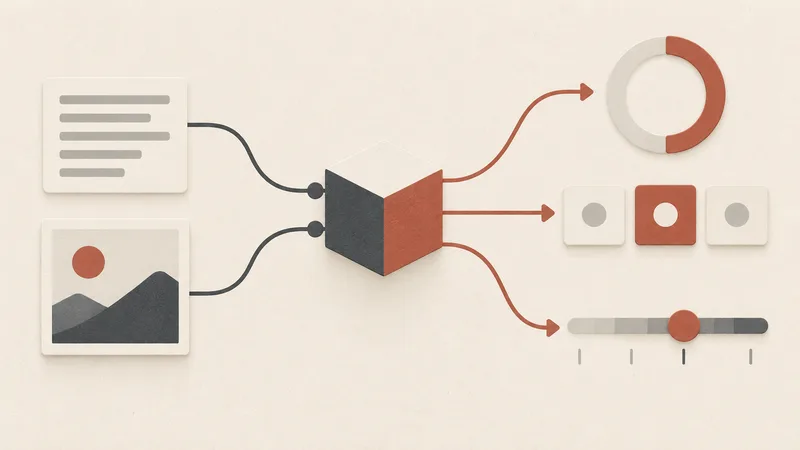
OpenAI opened its Decisions API to all developers in public beta on October 6, 2026, according to an announcement in the OpenAI Developer Community. The API guide describes an endpoint that turns text or image evidence into typed answers for classification, routing, or prioritization. GPT-6 Luna is the only model listed for the beta.
OpenAI’s speed wording differs between its two launch sources. The API guide says “10x faster than the Responses API”; the community announcement says “up to 10x faster than GPT-6 Luna through the Responses API.” Neither page gives the workload or benchmark method, so the claims need testing on an application’s own inputs.
A Hacker News submission linking to the guide showed 391 points and 231 comments at 19:34 UTC on October 11. One commenter, armcat, described 1,000-trial coin and marble experiments. For a marble outcome with a 50% chance, the commenter reported an 86% choice probability that moved to 73% after the option order changed. That is one participant's informal report, not a general benchmark, but it gives developers a reason to test whether order affects their own questions.
What the three outputs return
The endpoint returns a predicate, choice, or score for each question. A predicate estimates from 0 to 1 the probability that a statement is true, such as whether an image shows damage. A choice selects from supplied options and returns probabilities for those options plus a separate confidence value. A score rates the input against ordered levels and returns a probability-weighted average that can fall between levels.
These outputs suit fixed decision contracts. They give an application a value it can use for a route or threshold; they are not a written explanation or a custom response object. OpenAI points developers to Structured Outputs with the Responses API for JSON that follows their own schema, and to function calling when a model should request a tool call with arguments.
How a request is structured
The API reference defines a request with a model, shared input, and a list of questions. Input can be text or a user message with text and image parts; the reference allows up to 128 images across a request. It does not accept files, audio, function calls, or other message roles. Answers return in the same order as the questions. A choice question accepts between two and 255 unique options, while a score question uses ordered levels.
The answer shape also depends on the question type. A predicate answer contains a probability; a choice answer includes the selected value, confidence, and a probability for each option; a score answer includes its score and probabilities for the supplied levels. Application code should read the field that matches the returned type.
The API reference also defines a refusal result, which can replace an answer for a question. Applications should handle that branch explicitly and choose whether to retry, send the item for human review, or skip the automated decision rather than assuming every request returns the expected type.
Independent questions about the same input can share one request. When a later question depends on an earlier answer, OpenAI's guide says to send a separate request. This distinction affects how an application should divide a decision flow.
Beta limits, price, and evaluation
The guide says general availability is expected in the coming weeks but gives no date. OpenAI also lists Zero Data Retention and HIPAA use for eligible customers, with regional processing and data-residency conditions that require checking against the account's agreements.
The guide recommends using labeled examples from the application to set thresholds and weighing the cost of false positives against false negatives. A returned probability should not be treated as a calibrated business likelihood until it has been checked against known examples. Developers can measure latency, decision errors, option-order sensitivity, and threshold behavior before routing live cases.
A useful evaluation set should resemble the text and images an application will see, including borderline cases near the proposed threshold. Keep some labeled examples aside for a final check after setting the threshold. For choice questions, rerun the same examples with options in a different order and compare both the selected value and its probabilities. Record errors separately by decision type so a strong average does not conceal a weak class.
The listed price is $0.10 per million input tokens. At that base rate, 10 million input tokens cost $1 before any regional or long-context multiplier. The endpoint has no cache-read, cache-write, or output-token charges, while regional-processing premiums and long-context input multipliers may apply. Those terms belong in a cost estimate alongside the service's beta status.
For a high-cost decision, a team may keep a human review step until its labeled tests support an automatic threshold. Decisions is a candidate when an application needs a probability, a fixed-option answer, or a rubric score from text or images. The model limit and beta label set the current scope; teams still need to measure how its outputs behave on their own examples.
Sources & further reading
- Decisions | OpenAI APIOpenAI · accessed Oct 12, 2026
- Decisions API is now available in Public BetaOpenAI Developer Community, Announcements · accessed Oct 11, 2026
- Decisions API is in public betaHacker News · accessed Oct 11, 2026
- OpenAI released their Decisions API today, so I made it try to predict the future against Jev, Clef and Polymarket (open source!)Reddit, r/AI_Agents · accessed Oct 11, 2026
- Create a decision | OpenAI API ReferenceOpenAI · accessed Oct 12, 2026